Queries
Saved queries read the runtime entities (and the stream data) of a tenant without writing GraphQL. You create them in the Explorer, run them, export their results and use them as data source for MeshBoards, Power BI and Grafana. The former Query Builder page no longer exists: queries are the Queries tab of the Explorer.
Opening the saved queries
Select Data > Explorer in the rail and then the Queries tab (address .../data/explorer/queries).
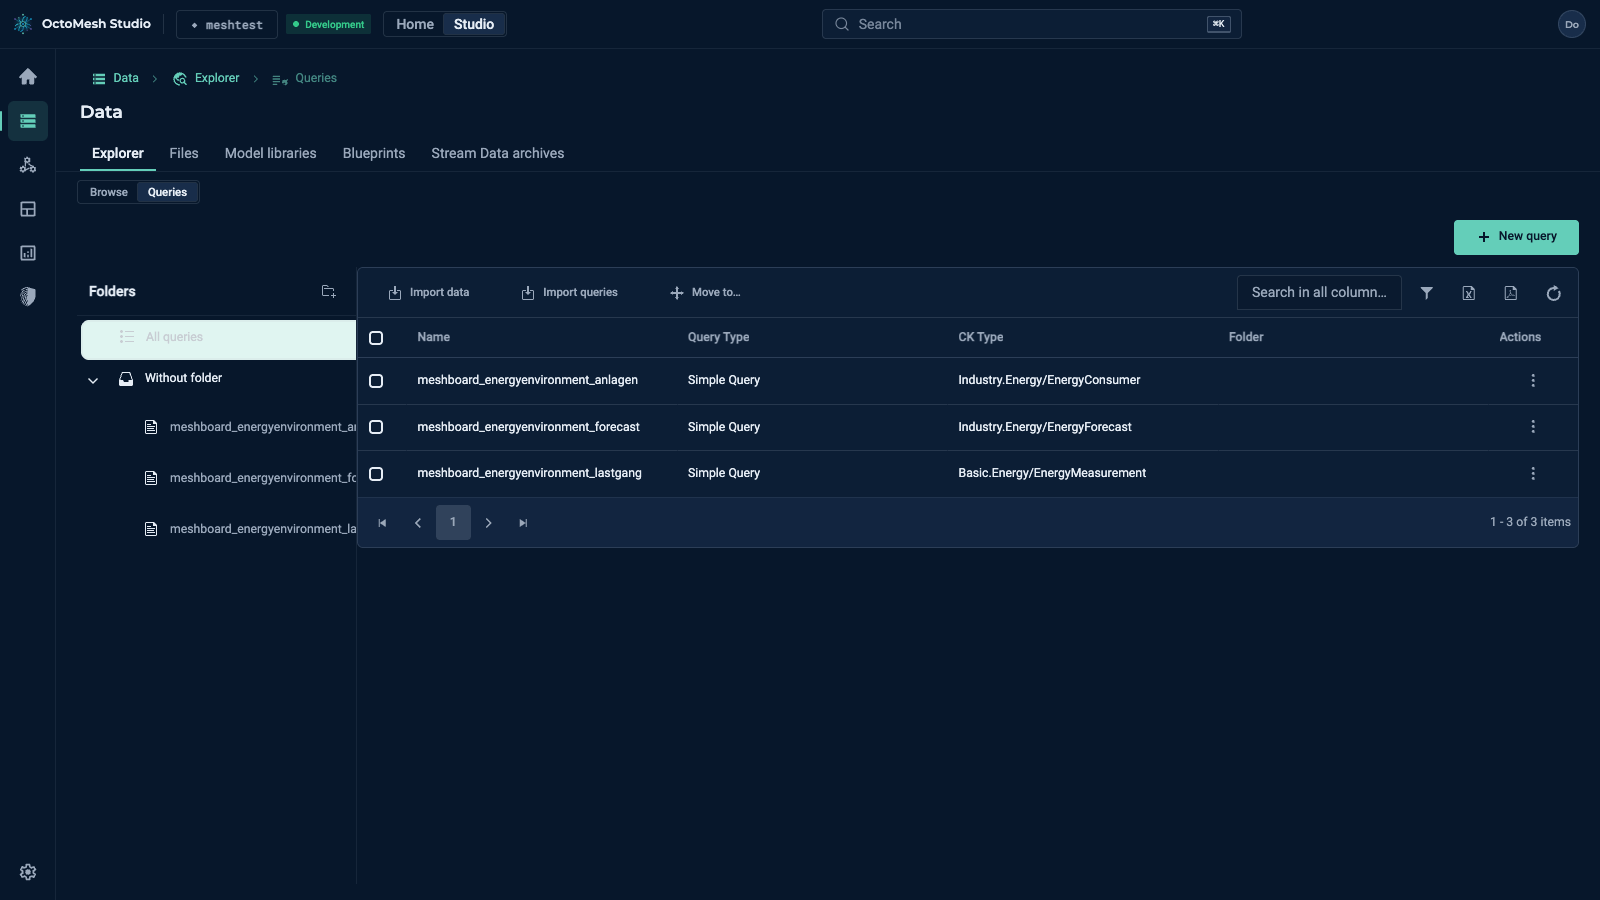
The page has the folder tree on the left (All queries, your folders, Without folder) and the list of queries on the right with the columns Name, Query Type, CK Type, Folder and Actions.
Toolbar
| Button | Description |
|---|---|
| New query | Create a query (opens the editor) |
| New folder | Create a folder for queries (needs the role AdminPanelManagement) |
| Import data | Import data from a file |
| Import queries | Import query definitions from a file |
| Move to… | Move the selected queries into a folder |
| Show Row Filter, Export to Excel, Export to PDF, Refresh Data | Filter, export or reload the list |
Folders can be nested; drag a query onto a folder or use Move to…. A query is in at most one folder. Deleting a folder moves its queries and subfolders one level up; queries are never deleted with a folder.
Row actions
Actions at the end of a row opens a menu:
| Action | Description |
|---|---|
| Edit | Open the query in the editor |
| Run | Run the query and show the result |
| Duplicate | Create a copy |
| Move to… | Move the query into a folder |
| Export results | Run the query and export the result as a ZIP file |
| Export query | Export the query definition as a ZIP file |
| Delete | Delete the query (with confirmation) |
Click the name of a query to run it.
The result page
Run opens the result in a grid with Back to list, Edit query, Refresh and Export. The row action Open in Explorer opens the entity in the Explorer. For a simple query, a click on a row opens the entity next to the result (details, associations, type); the address then ends with ?entity=<rtId>, so you can share it. Results of aggregations and stream data have no entities and do not open.
Creating a query
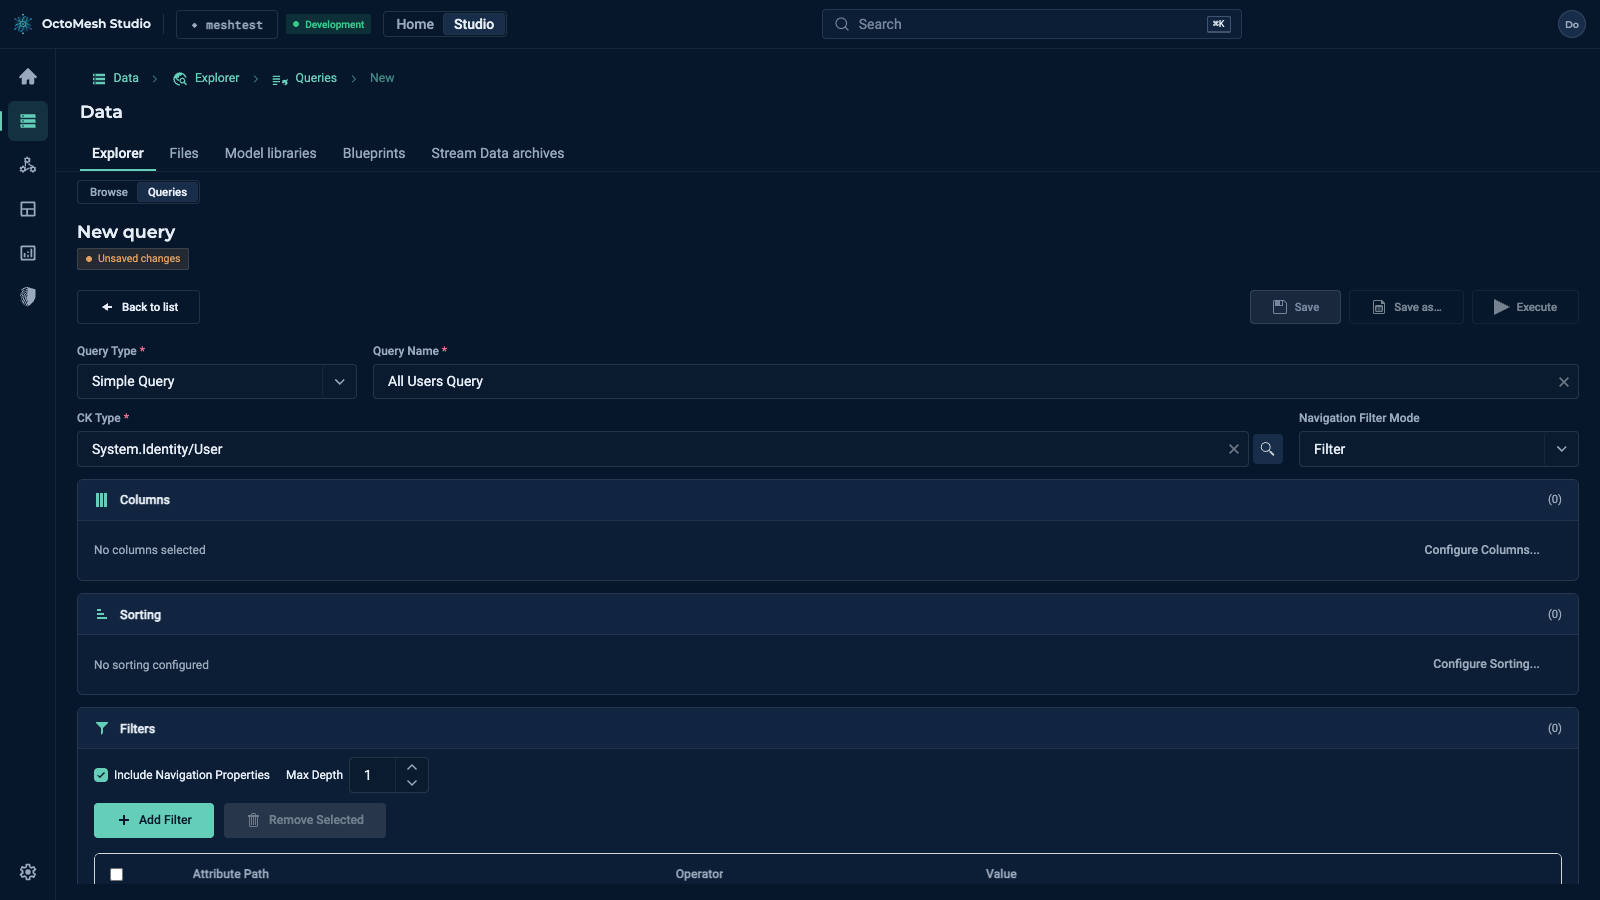
Click New query. The editor opens with the title New query; while there are unsaved changes the badge Unsaved changes is shown.
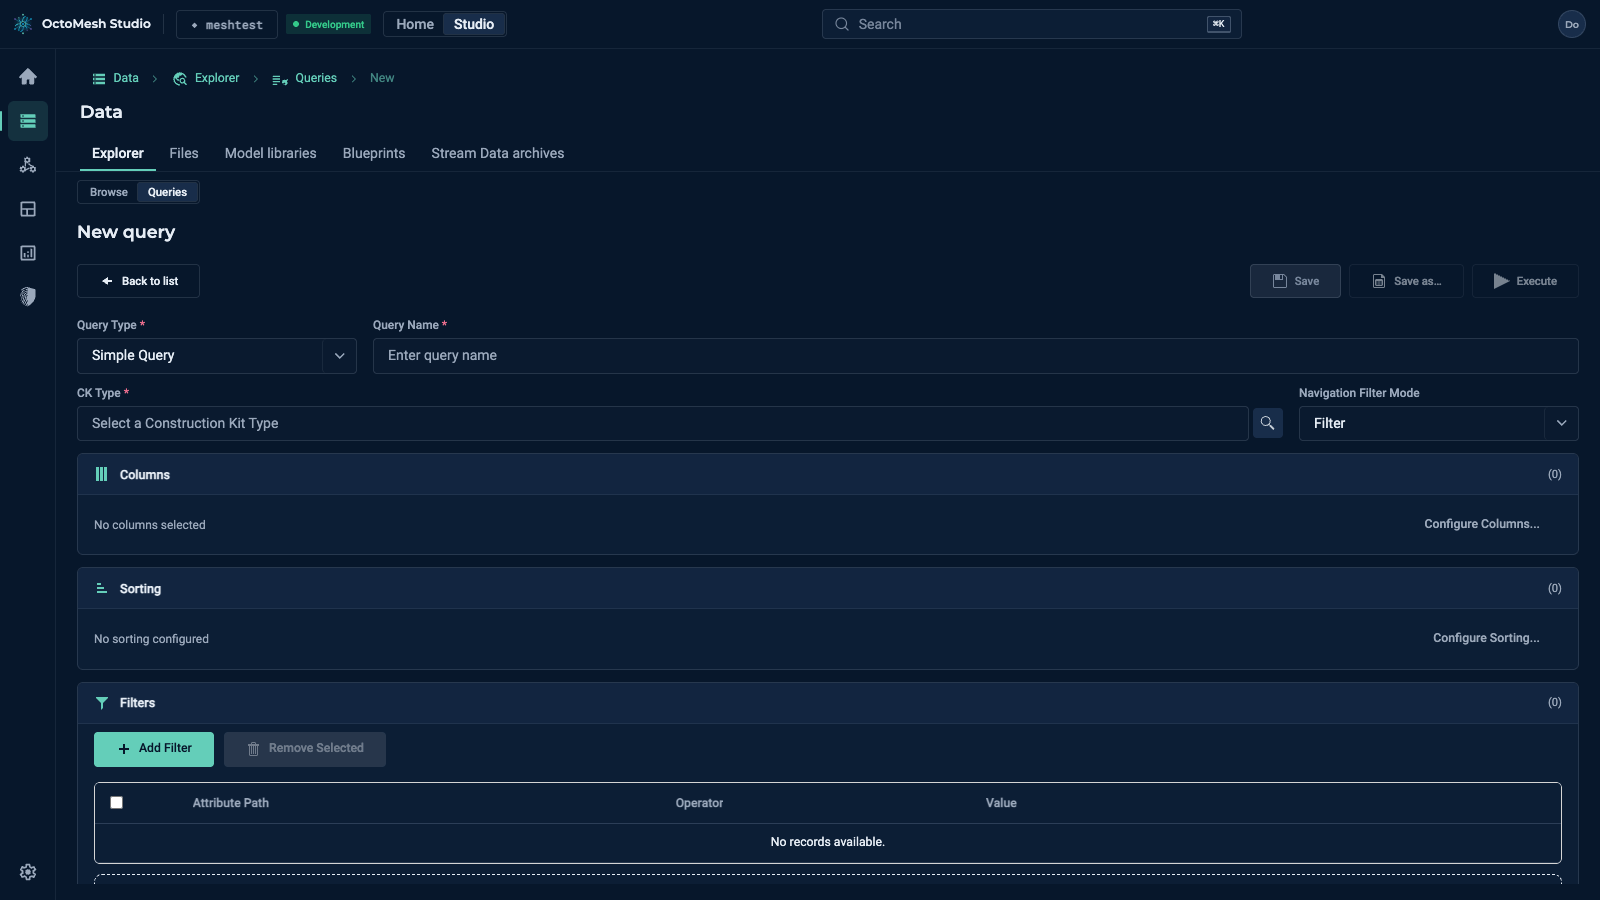
The buttons above the form are Back to list, Save, Save as… and Execute. A preview of the result appears below the form (Query Results Preview).
Basic settings
| Field | Description |
|---|---|
| Query Type | The kind of query (see below) |
| Query Name | A descriptive name (required) |
| CK Type | The Construction Kit type to query (required) |
| Navigation Filter Mode | How entities without matching navigation associations are handled |
Navigation Filter Mode
| Mode | Description |
|---|---|
| Filter | Entities without matching navigation associations are excluded from the result. |
| Include | Entities without matching navigation associations are kept with empty values. |
Query types
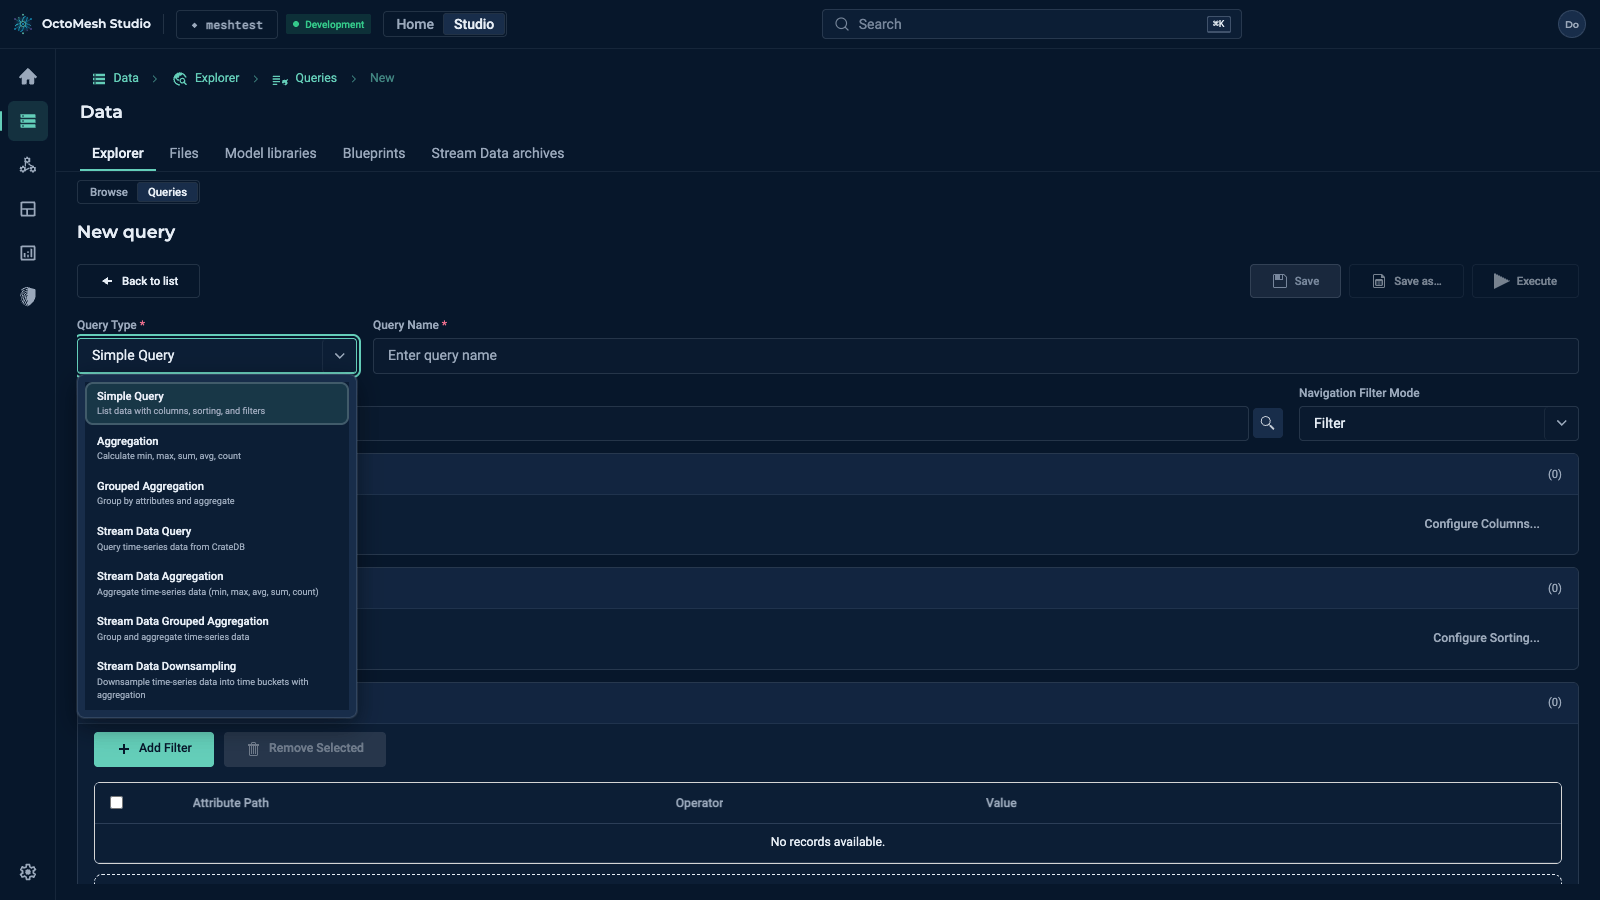
| Type | Description |
|---|---|
| Simple Query | List data with columns, sorting and filters |
| Aggregation | Calculate min, max, sum, avg, count |
| Grouped Aggregation | Group by attributes and aggregate |
| Stream Data Query | Query time-series data from CrateDB |
| Stream Data Aggregation | Aggregate time-series data (min, max, avg, sum, count) |
| Stream Data Grouped Aggregation | Group and aggregate time-series data |
| Stream Data Downsampling | Downsample time-series data into time buckets with aggregation |
Selecting a CK type
Click Select next to CK Type, or type in the field to get suggestions. Advanced Search... opens the dialog Select Construction Kit Type with a model filter, a type search and the list of types; confirm with OK.
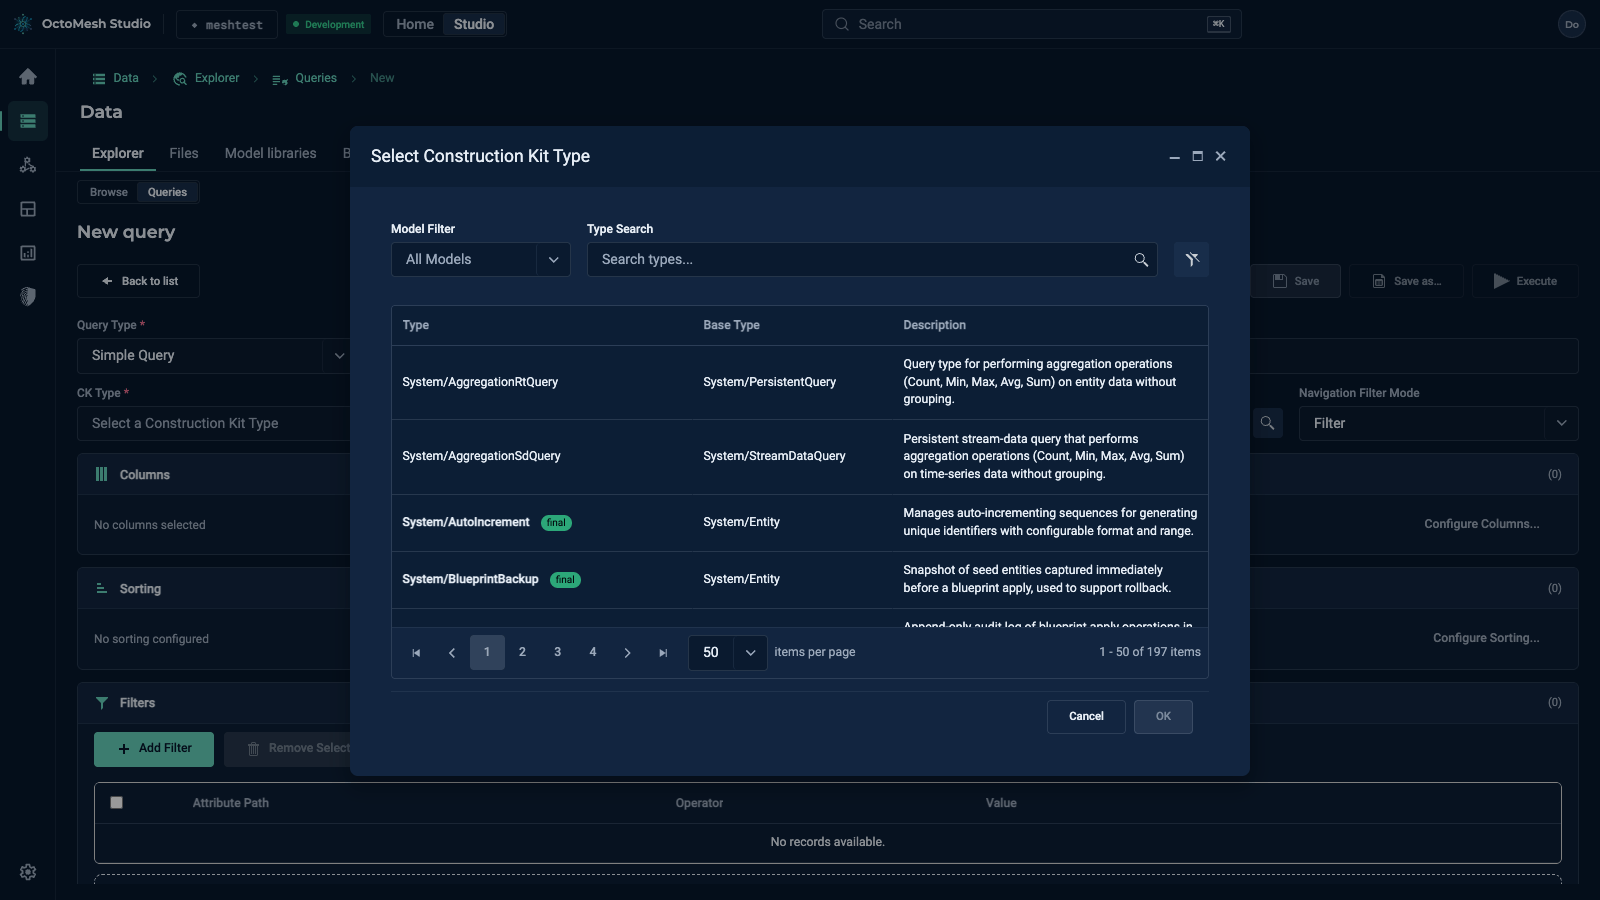
The other settings (columns, sorting, aggregation) stay disabled until a type is selected.
Simple query
For a simple query you configure columns, sorting and filters.
Columns
Click Configure Columns.... The dialog Select Columns lists the Available Attributes (attribute path, type, description) of the type, with a search field.
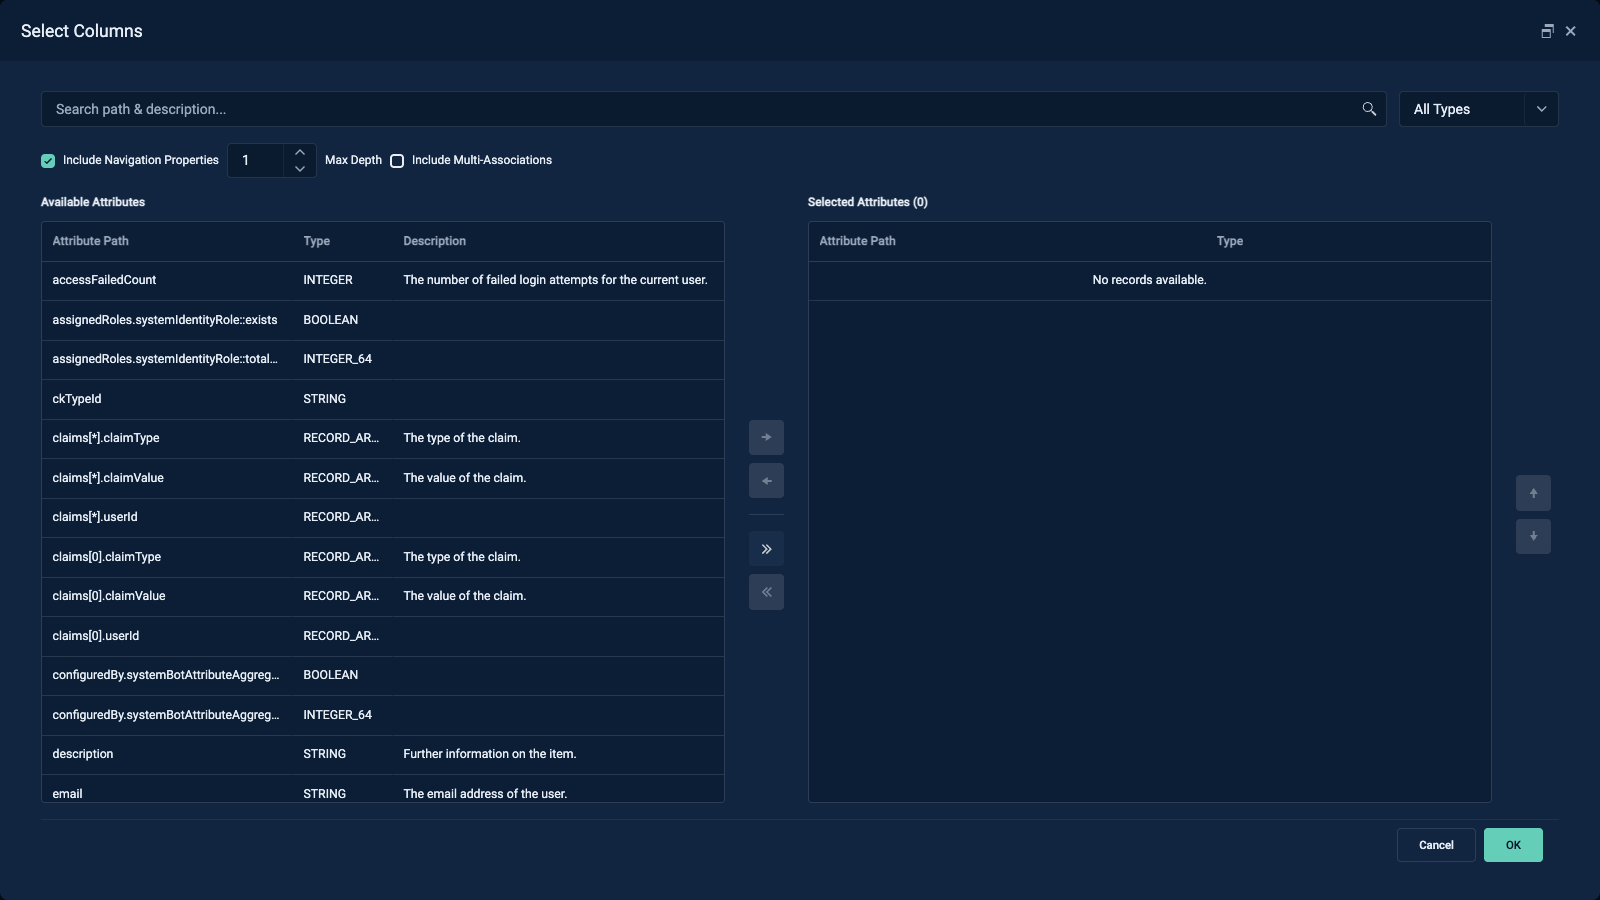
- Add selected, Remove selected, Add all and Remove all move attributes to the result columns.
- Move up and Move down change the order of the columns.
- Include Navigation Properties, Max Depth and Include Multi-Associations also offer attributes of associated entities (for example
namePlate.manufacturerName). - OK applies, Cancel discards.
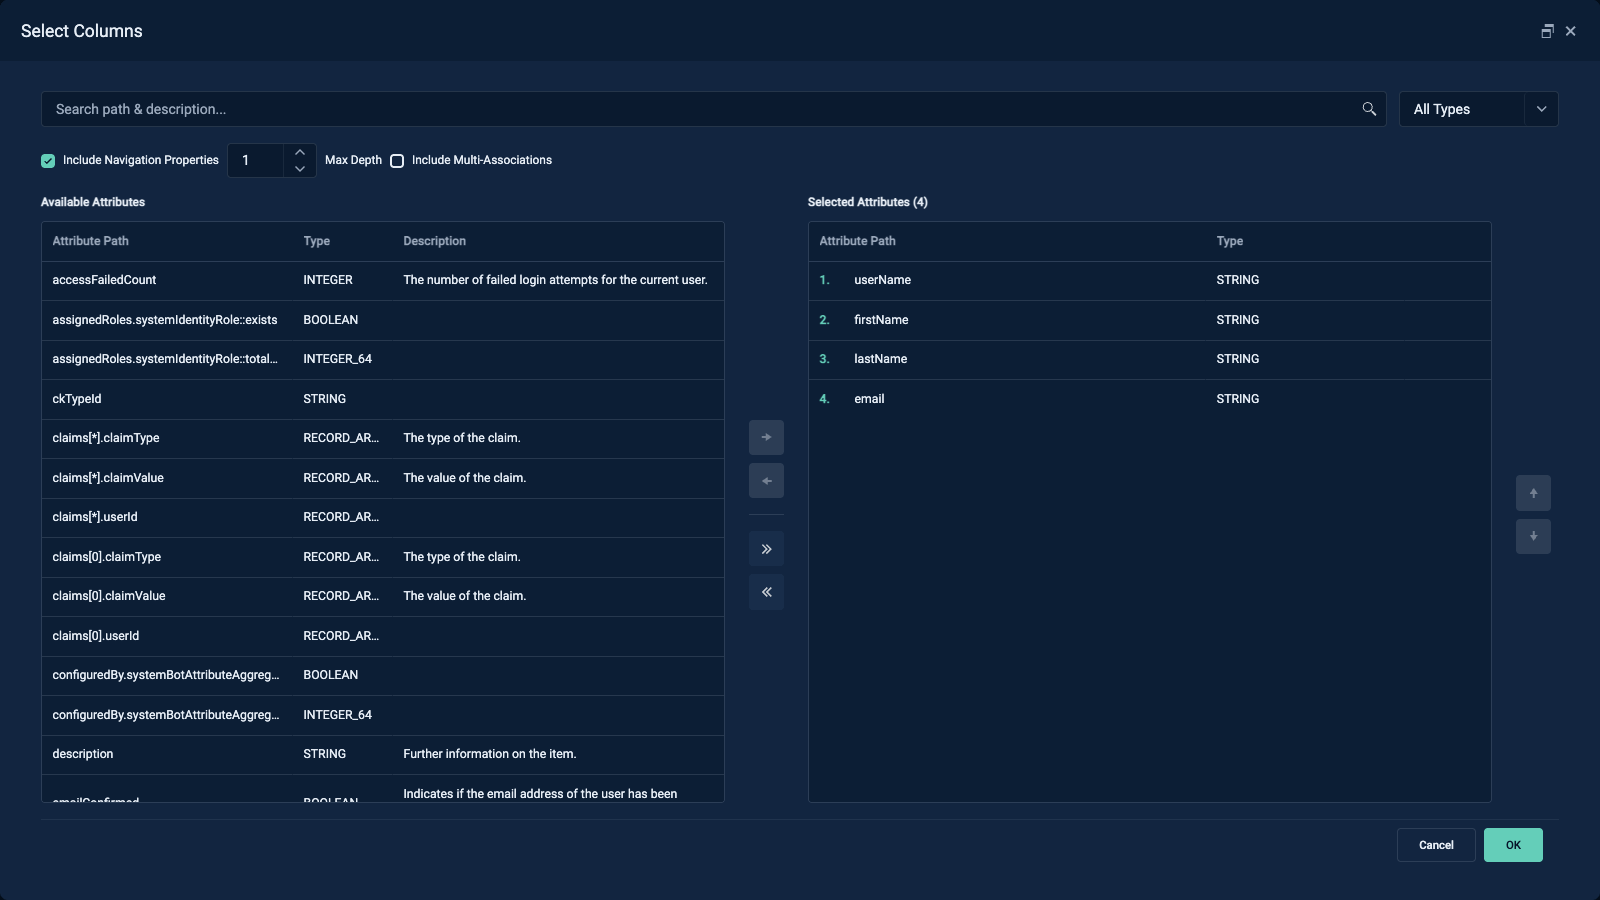
The form shows the chosen columns as a summary (for example "(5) name, machineState, power +2 more").
Besides the attributes of the type, the system fields rtDisplayName and rtDisplayDescription (computed from the display name rules of the type) can be used as columns, in filters and in sorting.
Attribute types: STRING, INTEGER, INTEGER_64, BOOLEAN, DATE_TIME, DATE_TIME_OFFSET, ENUM, STRING_ARRAY and RECORD_ARRAY.
Sorting
- Click Configure Sorting....
- Select an attribute and choose Ascending or Descending; Add → adds the rule.
- Click Apply.
Several rules are applied in the order of the list.
Filters
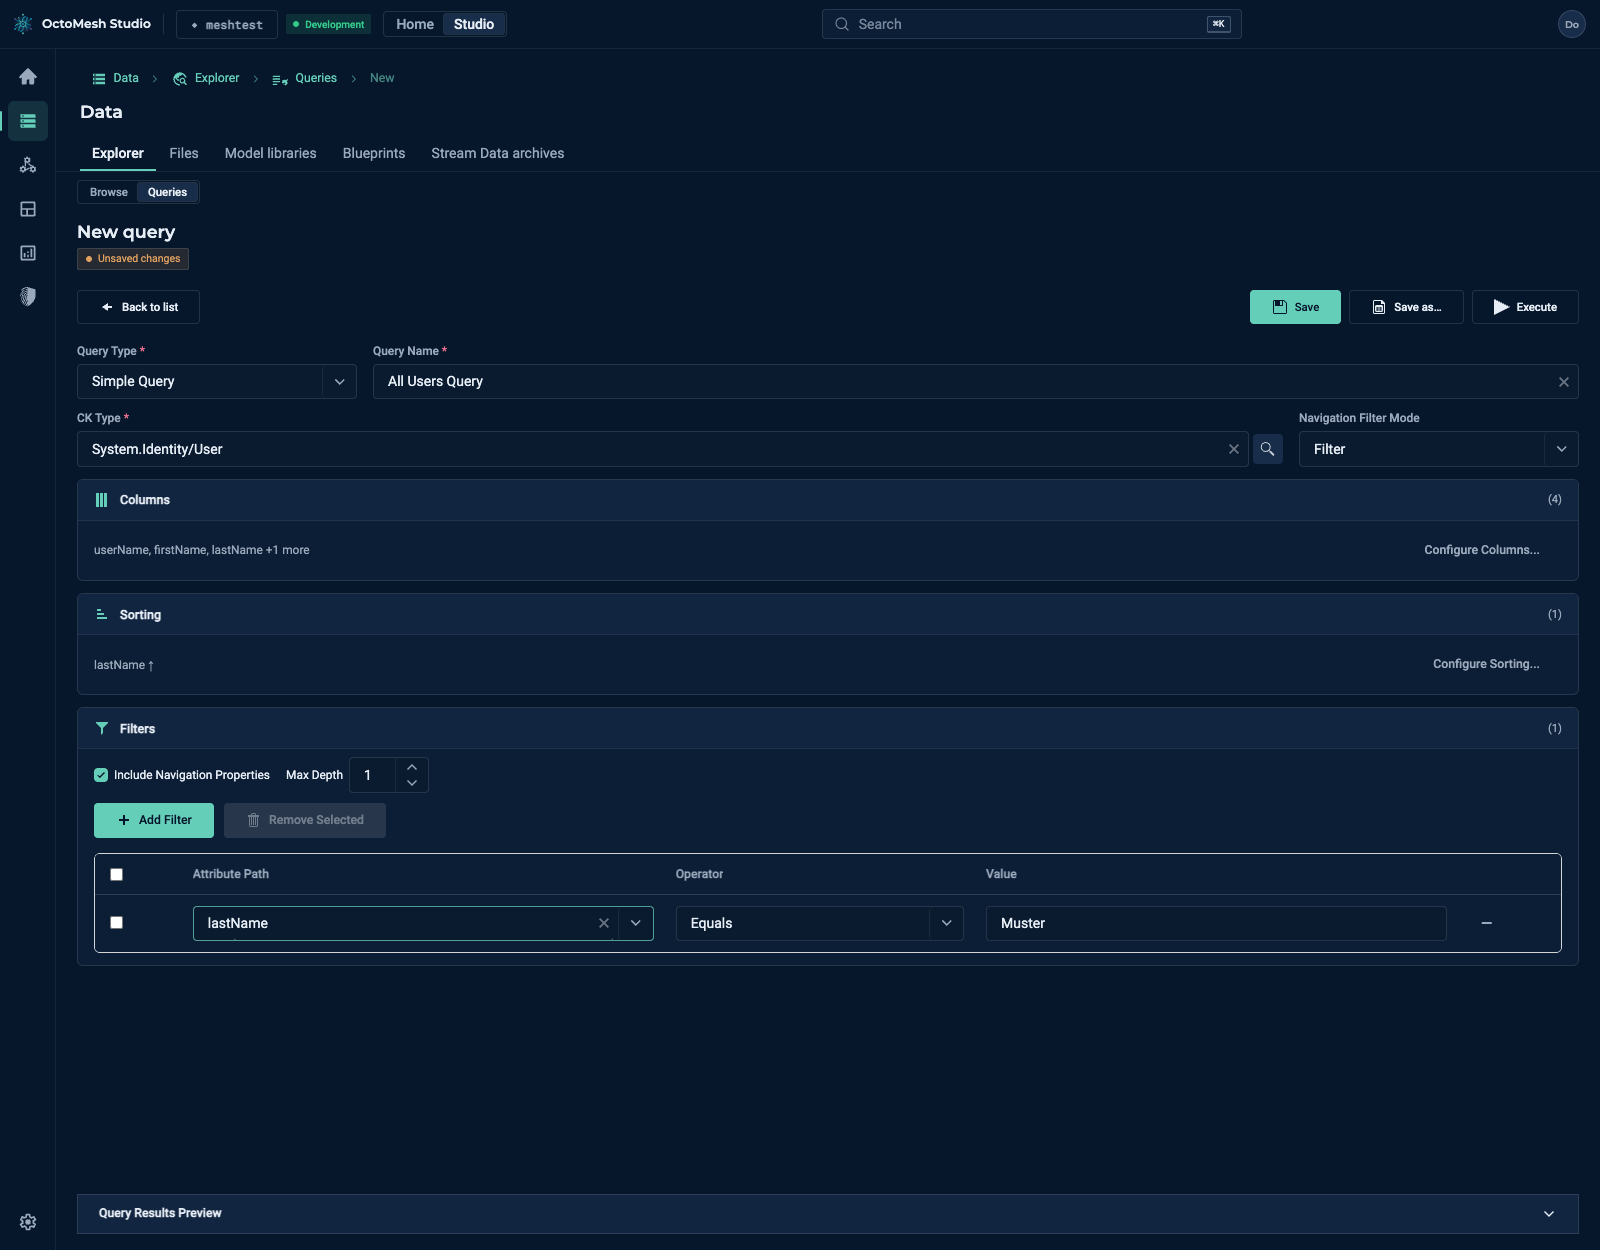
Filters narrow the result. Click Add Filter; a row appears in the table with the columns Attribute Path, Operator (default Equals) and Value. Remove Selected deletes the selected rows. Several filters are combined with AND.
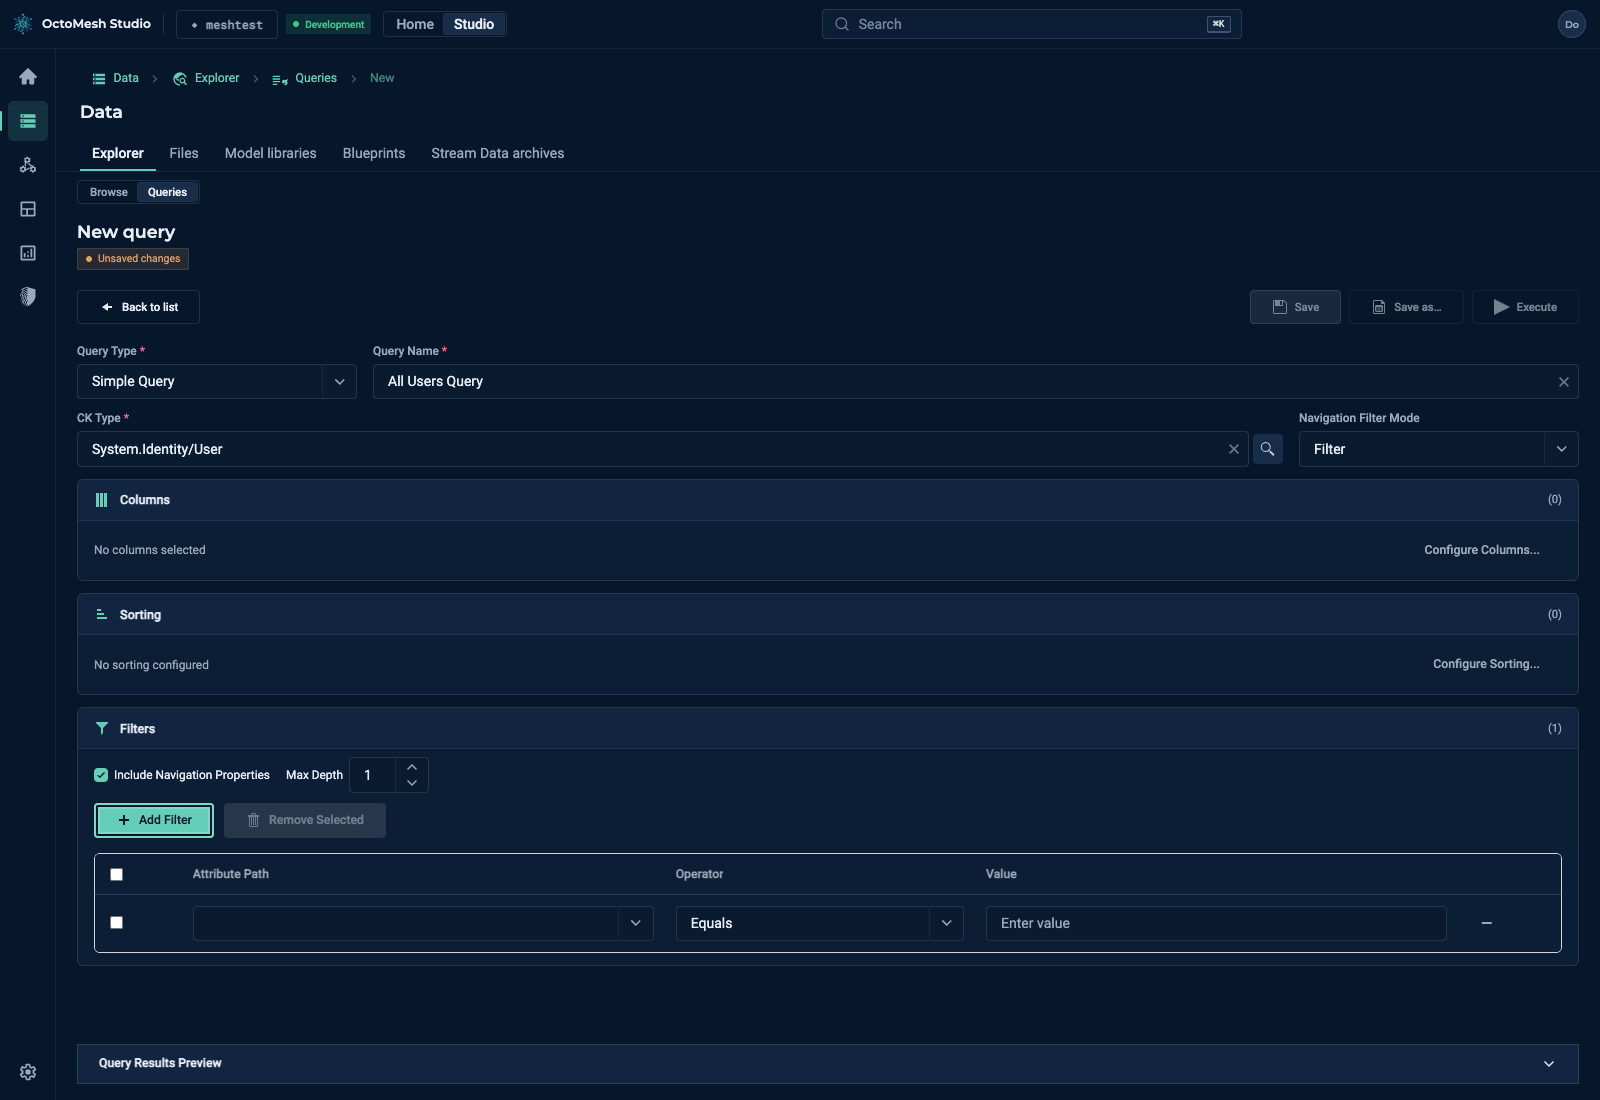
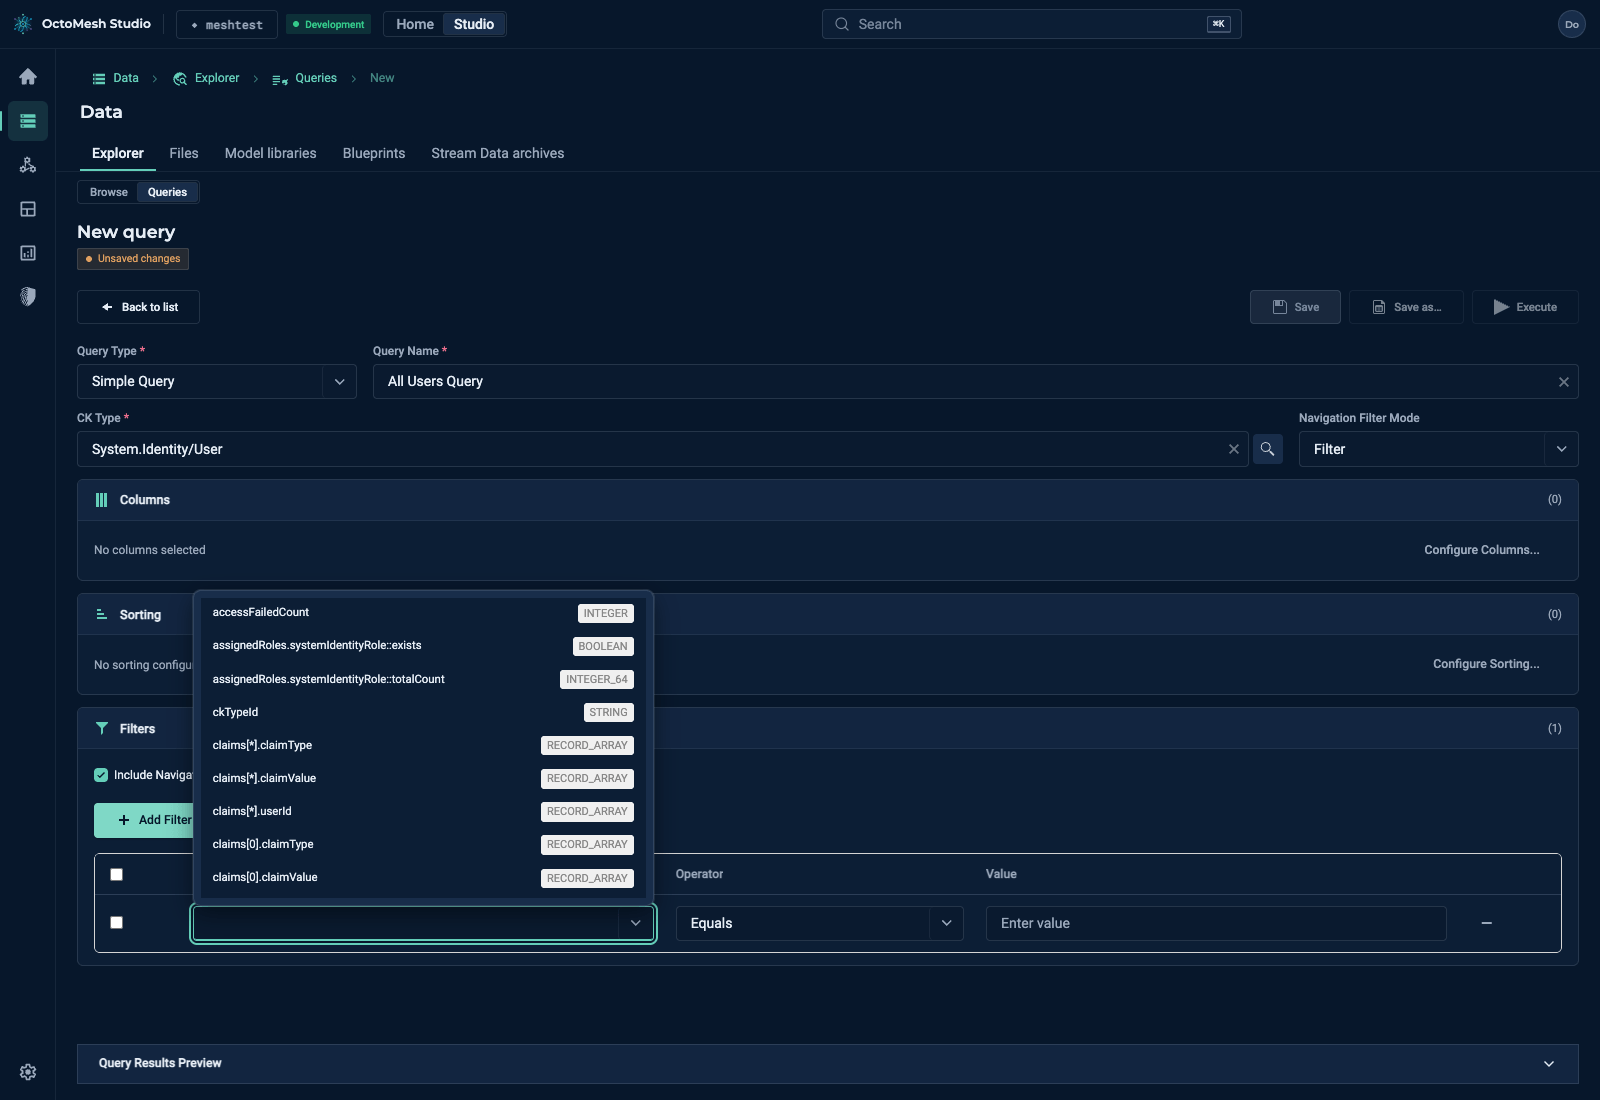
The value input follows the data type of the attribute: switch for boolean, text field for strings, number field for numbers, date picker for dates.
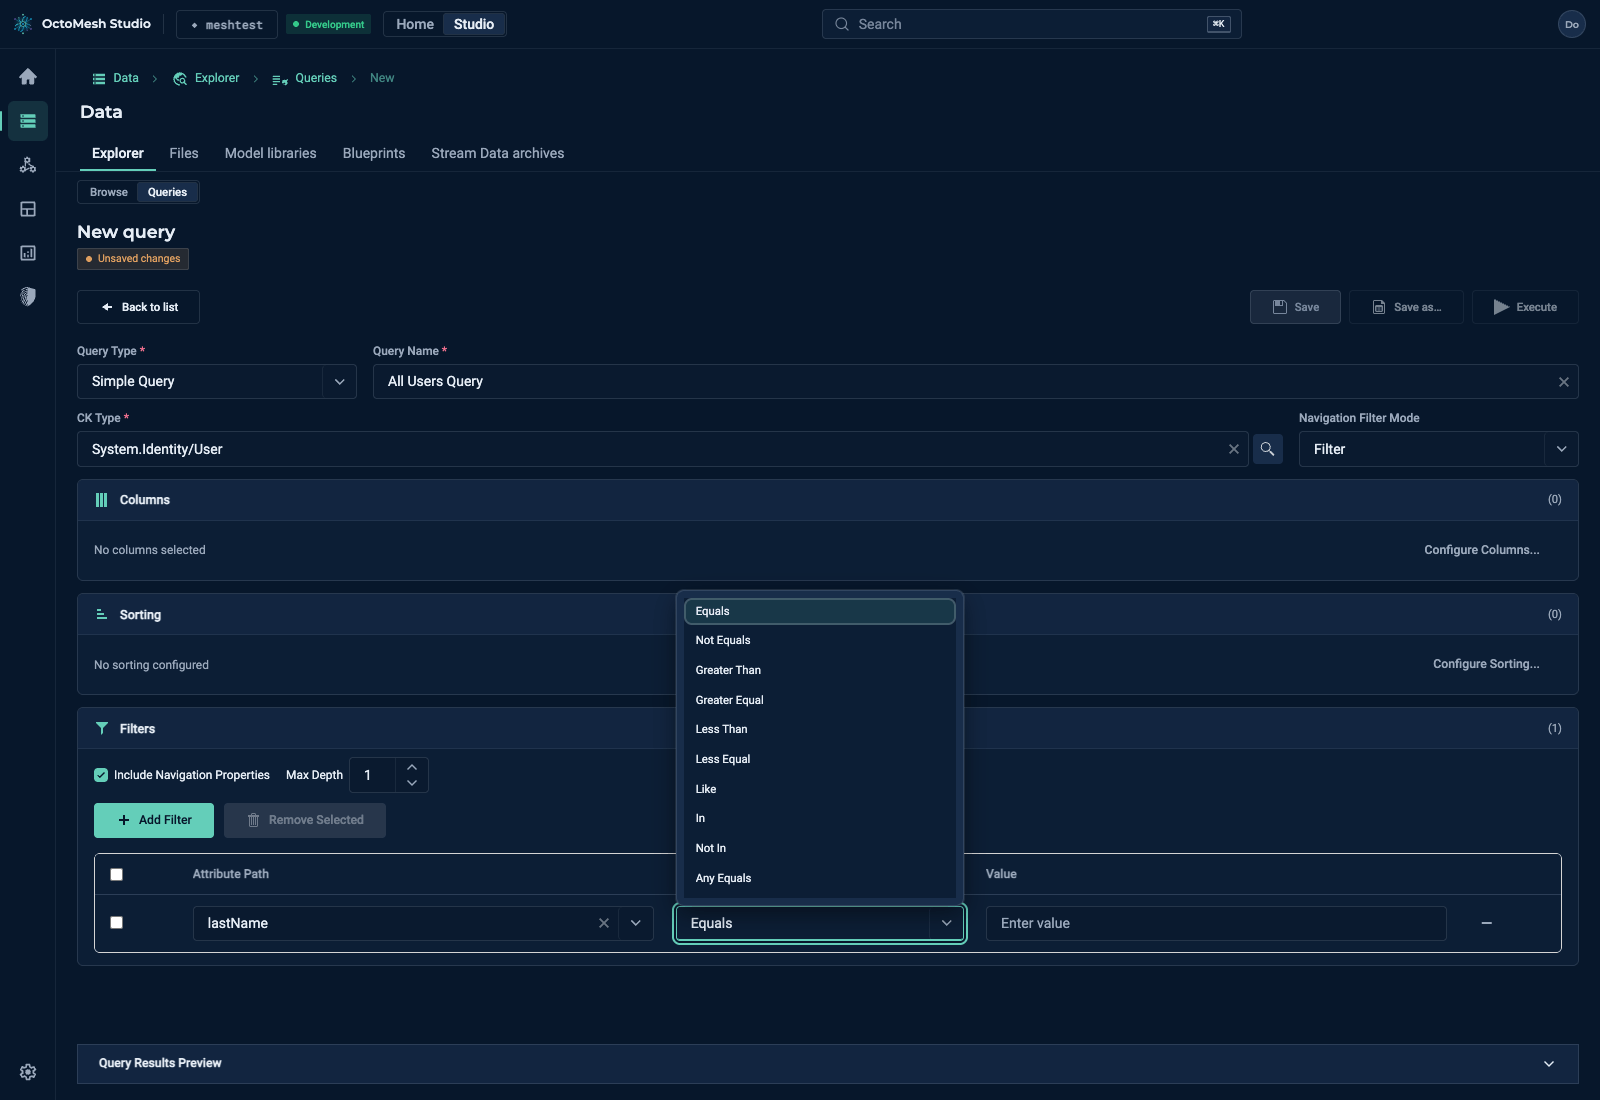
| Operator | Description |
|---|---|
| Equals | Exact match |
| Not Equals | Does not match |
| Greater Than | Value is greater than |
| Greater Equal | Value is greater than or equal to |
| Less Than | Value is less than |
| Less Equal | Value is less than or equal to |
| Like | Pattern match (use % as wildcard) |
| In | Value is in a list |
| Not In | Value is not in a list |
| Any Equals | Any array element matches |
| Any Like | Any array element matches the pattern |
| Match RegEx | Regular expression match |
Aggregation queries
Aggregation queries calculate summary values instead of returning single entities. For the query types Aggregation and Grouped Aggregation, the sections Columns and Sorting are replaced by Aggregation. Configure Aggregation... opens the dialog (enabled after you selected a CK type).
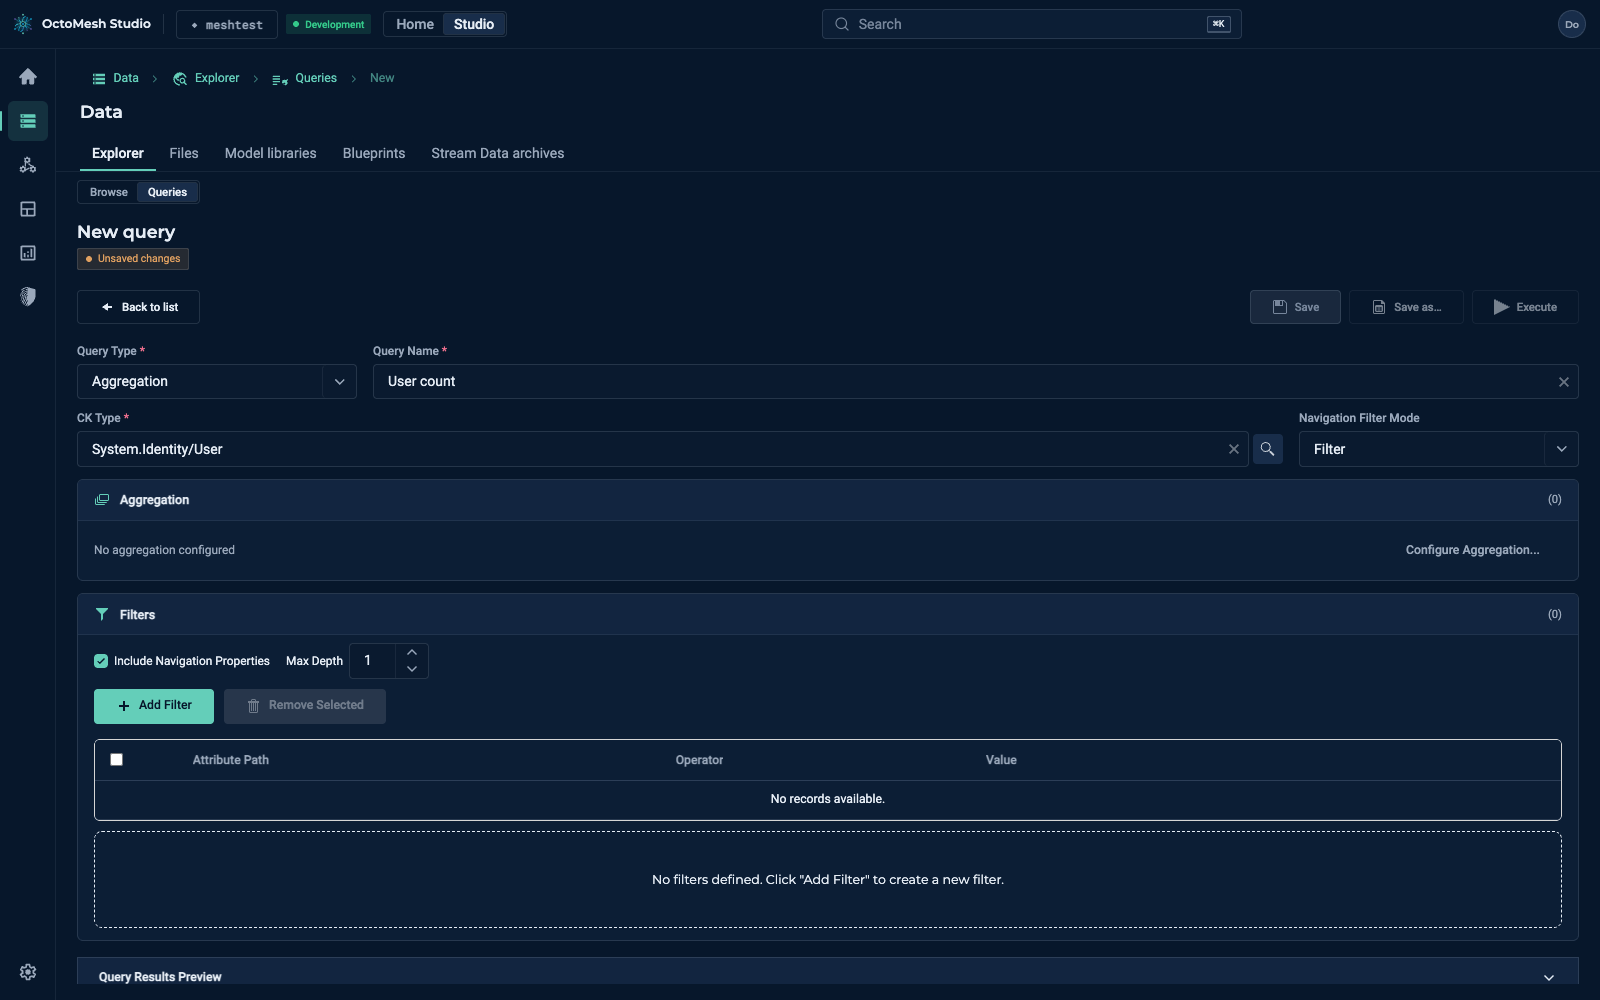
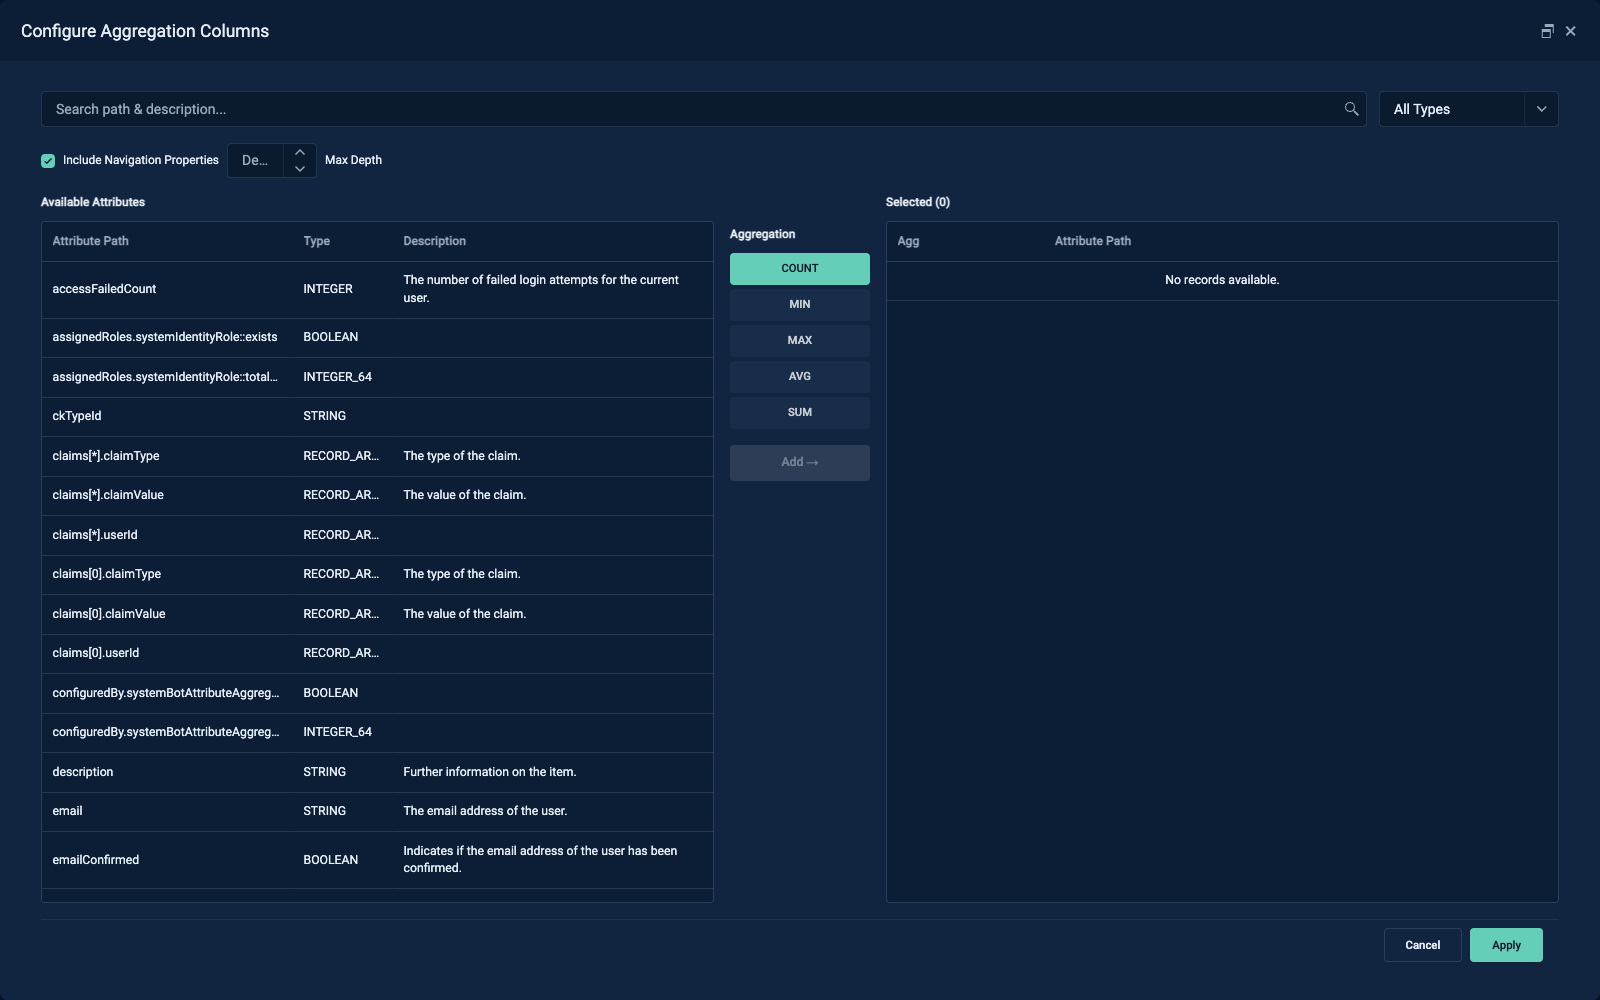
The dialog Configure Aggregation Columns lists the Available Attributes (attribute path, type, description) with a search field, the type filter All Types and the options Include Navigation Properties and Max Depth. In the middle, the buttons COUNT, MIN, MAX, AVG and SUM choose the function; Add → adds the selected attribute with that function to the list Selected on the right, whose columns are Agg and Attribute Path. Confirm with Apply, discard with Cancel. The dialog has no field for a name of the result column.
A Grouped Aggregation additionally has Group By: the result has one row per value of the grouping attribute, for example the number of users per department.
You also get here from the Explorer: Aggregate… opens a new query of type Aggregation with the selected type, the columns and the filter chips already filled in.
Running and saving
- Execute runs the query and shows the result in the preview below the form.
- Save stores the query; Save as… stores it under a new name. From the Explorer, Save as query creates a simple query for the selected type (you enter a name; names are unique).
- Saved queries can be run from the list, used in MeshBoard widgets and read by external tools such as Power BI or Grafana.
Stream Data Queries
In addition to runtime entity queries, the query editor supports querying time-series data stored in CrateDB. Stream data queries let you retrieve, aggregate, and downsample historical measurements such as sensor readings, machine metrics, or energy production values.
For the underlying GraphQL API details, see the Stream Data Access technology guide.
Stream Data Query Types
When creating a new query, the following stream data query types are available in the Query Type selector:
| Type | Description |
|---|---|
| Stream Data Query | Retrieve raw time-series data points with column selection |
| Stream Data Aggregation | Compute aggregated values (AVG, MIN, MAX, COUNT, SUM) across time-series data |
| Stream Data Grouped Aggregation | Aggregate time-series data grouped by one or more columns |
| Stream Data Downsampling | Reduce data density by bucketing time ranges with per-bucket aggregation |
Selecting a CK Type for Stream Data
When a stream data query type is selected, the CK Type selector only shows types that have stream data enabled (IsStreamType). Select the type whose time-series data you want to query (e.g., Industry.Energy/EnergyMeter).
Stream Data Simple Query Configuration
For stream data simple queries, the configuration is similar to runtime simple queries:
- Columns: Select which data stream attributes to include in the results (e.g.,
voltage,power). Only attributes marked as data stream attributes are available. - Time Range: Use the From and To date pickers to restrict the query to a specific time window.
- Limit: Set the maximum number of data points to return.
- Sorting: Add sort rules to control the order of results (e.g., sort by
timestampdescending for most recent first). - Filters: Add field filters to narrow results based on attribute values, using the same operators as runtime queries.
Stream Data Aggregation Configuration
For stream data aggregation queries:
- Aggregation Columns: Select attributes and assign an aggregation function to each:
- AVG — average value
- MIN — minimum value
- MAX — maximum value
- COUNT — number of data points
- SUM — sum of values
- Time Range: Optional from/to restriction.
- Limit: Maximum rows to return.
- Filters: Optional field-level filters applied before aggregation.
Stream Data Grouped Aggregation Configuration
For stream data grouped aggregation queries:
- Group By: Select one or more attributes to group results by (e.g., group by
rtIdto get per-entity aggregations). - Aggregation Columns: Same as aggregation queries — select attributes with aggregation functions.
- Time Range, Limit, and Filters: Same as above.
Stream Data Downsampling Configuration
Downsampling divides a time range into equal-sized buckets and computes an aggregation per bucket. This is ideal for chart and dashboard visualizations.
- Aggregation Columns: Select attributes with aggregation functions (AVG, MIN, MAX).
- From and To: Required — define the time range to downsample.
- Limit: Required — the number of time buckets to produce. The bucket size is calculated as
(to - from) / limit. For example, a 24-hour range with limit 24 produces hourly buckets. - Filters: Optional field-level filters.
Executing and Viewing Stream Data Results
Click Execute to run the stream data query. Results are displayed in a table format with:
- Timestamp: The time of each data point (or bucket start for downsampling)
- Entity: The runtime entity (
rtId/rtWellKnownName) the data belongs to - Data columns: The requested attribute values or aggregated results
Results support pagination for large datasets.
Saving Stream Data Queries
Click Save to persist the stream data query. Saved stream data queries can be:
- Re-executed from the list of saved queries
- Used as data sources in MeshBoard widgets (KPI, Gauge, Chart, Table)
- Referenced by external tools such as Power BI or Grafana
Best Practices
- Name queries descriptively: Use clear names that indicate what the query returns
- Use filters effectively: Narrow down results to improve performance
- Select only needed columns: Include only attributes you need to reduce data transfer
- Test before saving: Execute the query to verify results before saving
- Use aggregations for summaries: Use aggregation queries instead of fetching all data and calculating client-side
- Consider performance: Complex queries on large datasets may take longer to execute
- Use downsampling for charts: When visualizing time-series data on dashboards, use downsampling to reduce data points to a manageable number matching your chart resolution
- Set time ranges: For stream data queries, always set a time range to avoid querying the entire history
Use Cases
Data Exploration
- Browse entities of a specific type
- Search for entities matching criteria
- View entity attributes and relationships
Time-Series Analysis
- View historical sensor readings for a specific machine
- Compare voltage trends across multiple energy meters
- Identify anomalies in measurement data
Reporting
- Count entities by status
- Calculate averages and totals
- Group and summarize data
- Generate periodic summaries of time-series metrics
Dashboard Data Sources
- Create queries for MeshBoard widgets
- Build reusable data extractions
- Set up filtered views for specific use cases
- Use downsampling queries for time-series chart widgets
Power BI Integration
- Use saved queries as data sources for Power BI reports and dashboards
- Leverage aggregation queries for pre-calculated summaries in Power BI
Grafana Integration
- Connect saved queries to Grafana dashboards for real-time monitoring
- Use aggregation queries for time-series and metric visualizations